Asset Reliability &
Maintenance

Focus maintenance effort on the assets and failure modes that matter.

Risk-based engineering support for industrial electrical systems.
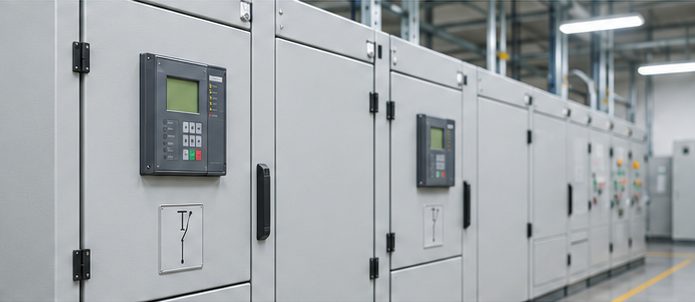
Row of electrical switchgear cabinets with protection relays in an industrial facility

A structured approach to asset reliability

RCM Strategy

Define maintenance tasks around asset function and failure modes.

Criticality & FMECA

Identify the consequences that drive maintenance priorities.

Maintenance Optimization

Review tasks, intervals and the existing programme.

System Reliability

Connect equipment decisions with wider operating requirements.

Inputs we review

Asset registers · maintenance history · failure records · operating context.

Typical outputs

Criticality rankings · task recommendations · maintenance frameworks.

Recommendations depend on the available data and agreed scope.

In detail: what the work covers

RCM Strategy Development

Reliability Centred Maintenance replaces calendar-based routines with tasks chosen for how each asset actually fails and what happens when it does. For some equipment that means condition monitoring; for some it means a fixed interval; and for some the right answer is a deliberate run-to-failure policy.

What this covers

  • Asset register and boundaries — defining what is being analysed and where each system starts and stops.
  • Functions and functional failures — what each asset is required to do, and what counts as failing to do it.
  • Failure mode analysis — the ways each function is lost in practice, not in theory.
  • Consequence assessment — safety, environmental, operational and cost consequences of each failure mode.
  • Task selection — condition-based, time-based, failure-finding or run-to-failure, chosen against defined criteria.
  • Interval determination — task frequency set from failure characteristics rather than convention.
  • CMMS integration — output structured so it can be loaded into your maintenance management system.

Standards and references

Analysis follows SAE JA1011 and JA1012 for RCM process criteria, with reference to IEC 60300-3-11 for dependability management.

Criticality & FMECA Analysis

Not every asset deserves the same attention. FMECA establishes which failures actually threaten safety, production or compliance, so that maintenance effort and capital go where the consequences are greatest instead of being spread evenly across everything.

What this covers

  • Criticality ranking — a consistent scoring framework applied across the asset base.
  • Failure mode identification — the realistic ways each asset fails in your operating environment.
  • Effects analysis — local effect, system effect and end effect for each mode.
  • Consequence categories — safety, environmental, production, and repair cost assessed separately.
  • Detectability — whether a failure gives warning, and whether current monitoring would catch it.
  • Risk prioritisation — a ranked register that drives where to spend next.
  • Spares implications — which failure modes justify holding critical spares.

Standards and references

Analysis follows IEC 60812 for FMEA and FMECA technique, supported by ISO 14224 for equipment taxonomy and reliability data where oil and gas assets are in scope.

Maintenance Program Optimization

Most maintenance programmes accumulate tasks and rarely lose them. Optimization works from what you already do — reviewing task validity, interval, and value — rather than starting again, which usually makes it quicker to implement and easier for a maintenance team to accept.

What this covers

  • Task validity review — whether each existing task addresses a real failure mode.
  • Interval review — tasks being done more often than the failure characteristics justify, and less often than they should be.
  • Duplication — the same check performed under two different work orders.
  • Gap identification — significant failure modes with no task covering them.
  • Resource loading — how manpower is distributed against asset criticality.
  • Work order and history review — using your own maintenance records to find where effort is being wasted.
  • Condition monitoring — where a predictive technique would replace an intrusive routine.

Standards and references

Work references SAE JA1011 for maintenance task selection logic, IEC 60300-3-11 for dependability, and ISO 14224 for equipment taxonomy and failure data.

System-Wide Reliability Strategy

Reliability decisions made asset by asset tend not to add up to a reliable facility. A system-wide strategy looks at how the electrical network, the protection that guards it, and the rotating plant that depends on it interact — and where redundancy, monitoring or design change buys more availability than additional maintenance would.

What this covers

  • System reliability assessment — availability of the network as a whole, not just of individual assets.
  • Single point of failure identification — where one failure takes out more than it should.
  • Protection system reliability — dependability against security, and the testing regime that keeps both acceptable.
  • Rotating machinery strategy — condition monitoring across motors, generators and drives.
  • Redundancy evaluation — whether additional redundancy is justified by the availability it buys.
  • Interaction with power system studies — using load flow, stability and protection results as reliability inputs.
  • Improvement roadmap — sequenced actions with the availability impact of each.

Standards and references

Work references IEEE 493 for the reliability of industrial and commercial power systems, IEC 60300-3-11 for dependability management, and ISO 14224 for reliability data.

Which assets need a clearer maintenance strategy?

Discuss Your Facility